Webpage Content Extraction: A Practical Guide for Research, Content Analysis, and AI Workflows
WhisperChat’s Webpage Content Extractor helps users collect relevant webpage content from a URL, making online research and content analysis easier. It can support writers, marketers, researchers, and businesses that need to organize webpage information for further review.
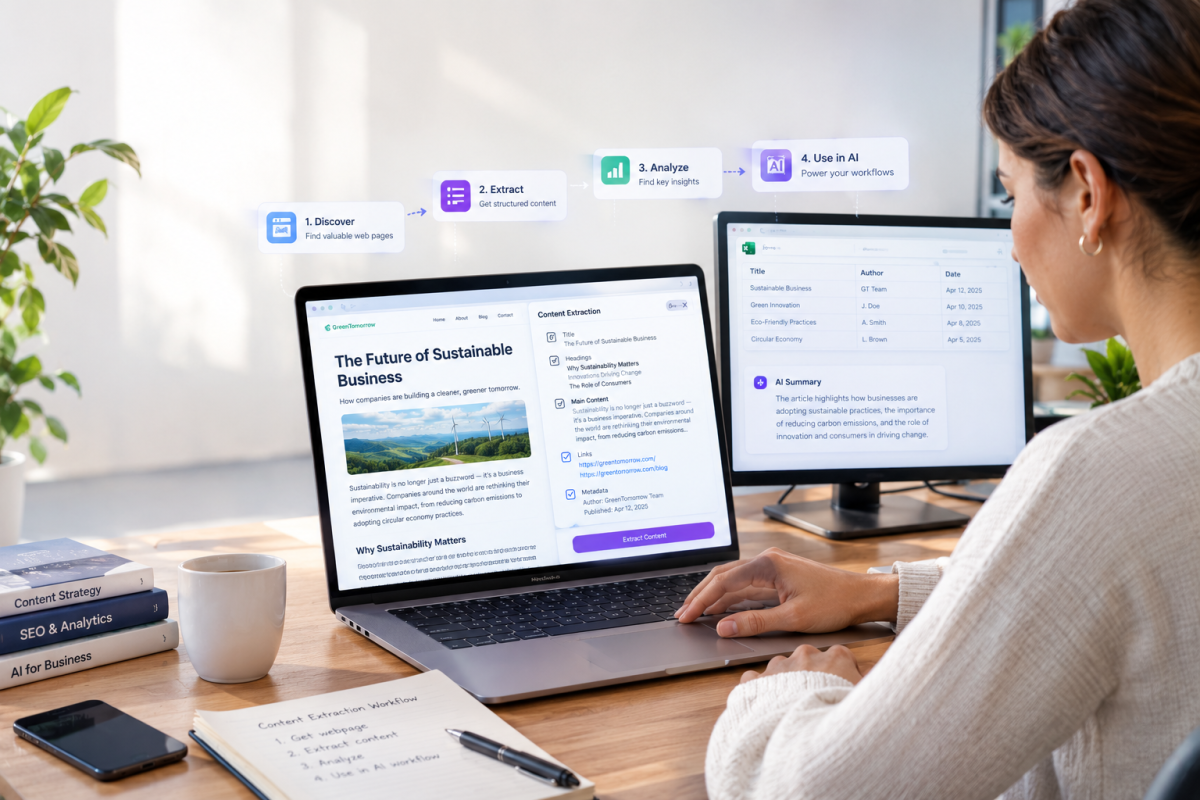
The web contains an enormous amount of useful information, but finding and organizing that information can take time. A typical webpage may include navigation menus, advertisements, buttons, images, scripts, footers, and other elements alongside the main content. When someone needs only the meaningful text from a page, manually copying and cleaning it can become repetitive.
A webpage content extractor can simplify this process by helping users collect relevant information from a webpage and prepare it for further review. Tools such as the WhisperChat Webpage Content Extractor can be useful for researchers, content teams, marketers, and businesses working with online information.
What Is Webpage Content Extraction?
Webpage content extraction is the process of identifying and collecting useful information from a web page while leaving out unnecessary elements.
For example, imagine that you are researching an article containing a long introduction, several headings, paragraphs, links, navigation menus, and unrelated page elements. If your goal is to analyze the article itself, copying the entire webpage may create unnecessary work.
Content extraction can help separate the information you need from the surrounding webpage structure.
Depending on the tool and configuration, extracted content may include:
-
Headings
-
Paragraphs
-
Lists
-
Links
-
Text content
-
Selected HTML elements
-
Specific sections of a webpage
This can make online research and content organization more manageable.
Why Is Webpage Content Extraction Useful?
People work with webpages for many different reasons. Researchers may need information for analysis, content teams may want to study published material, and businesses may need to organize website information for internal workflows.
Manually collecting information from every page can become inefficient, particularly when working with multiple sources.
A content extraction workflow can help users:
-
Save time during research
-
Focus on relevant page information
-
Organize online material
-
Analyze published content
-
Prepare information for further processing
-
Reduce repetitive copy-and-paste tasks
The value comes from making information easier to work with rather than simply collecting as much content as possible.
Common Uses for a Webpage Content Extractor
1. Online Research
Researchers frequently work with multiple websites when investigating a subject. Extracting relevant text can make it easier to review information without repeatedly navigating through the same page elements.
For example, someone researching a technology topic might collect relevant articles from several websites and organize the extracted material for comparison.
The researcher can then manually review the sources and identify important themes, differences, and supporting information.
2. Content Analysis
Content marketers and SEO professionals often analyze webpages to understand how competitors approach a particular topic.
A webpage content extractor can provide a cleaner starting point for this analysis.
You might examine:
-
Main headings
-
Subheadings
-
Topic coverage
-
Frequently discussed concepts
-
Content structure
-
Frequently linked resources
The goal should not be to copy another website's content. Instead, extracted information can help you understand how a topic has already been covered and identify opportunities to provide something more useful or original.
3. Preparing Information for AI Workflows
Businesses increasingly use AI tools to process internal and publicly available information. Before information can be reviewed by an AI system, it may need to be collected and organized.
Extracting relevant webpage content can provide a cleaner input for certain workflows.
For example, a team researching a software category might collect publicly available product information and organize it before analyzing common features, pricing structures, or customer-facing messaging.
The extracted material should still be reviewed for accuracy, relevance, and appropriate use.
4. Building Research Notes
Students, writers, and researchers often save useful information from webpages for future reference.
Instead of manually copying sections into a document, a content extraction tool can help create a starting point for research notes.
The resulting information can then be reorganized into:
-
Summaries
-
Topic outlines
-
Research notes
-
Comparison documents
-
Content briefs
This can make the early research stage more efficient.
How a Webpage Content Extractor Works
The general process is relatively straightforward.
Step 1: Enter a Webpage URL
The user begins with the URL of the webpage they want to examine.
The page should be publicly accessible and suitable for the intended research or workflow.
Step 2: Choose the Information to Extract
Depending on the tool, users may be able to configure which parts of the webpage should be included.
For example, someone may want text content primarily while excluding navigation, unnecessary sections, or other page elements.
This filtering step can help produce a cleaner result.
Step 3: Process the Page
The extraction system processes the webpage and identifies the requested information.
Instead of manually selecting and copying content, the tool handles the initial collection process.
Step 4: Review the Result
Extraction does not eliminate the need for human review.
Webpages can contain unusual layouts, dynamically generated information, tables, embedded content, or sections that may not be interpreted exactly as expected.
Always check the extracted result against the original webpage when accuracy matters.
Using Extraction for SEO Research
SEO professionals can use webpage extraction as part of a broader research process.
Suppose you are preparing an article about AI customer support. You may want to understand how existing pages approach the subject.
You could examine several relevant pages and look for:
-
Topics covered across multiple sources
-
Questions readers may have
-
Content gaps
-
Common terminology
-
Different explanations of the same concept
-
Supporting resources
This can help with content planning.
However, extraction should support original content creation, not duplication.
A strong SEO article should contribute its own explanations, examples, analysis, experience, or research rather than simply reproducing information found elsewhere.
Webpage Extraction and Content Quality
One of the biggest benefits of extraction is organization. It can make large amounts of information easier to review.
However, collecting information is only the beginning.
High-quality content still requires:
-
Fact checking
-
Source evaluation
-
Original analysis
-
Clear writing
-
Proper attribution
-
Logical organization
-
Reader-focused explanations
For example, extracting ten competitor articles does not automatically produce a useful SEO strategy. Someone still needs to interpret those sources and determine what information is reliable and what readers actually need.
This distinction is particularly important for businesses using AI-assisted content workflows.
How Content Teams Can Use the Tool
Content teams can incorporate webpage extraction into several stages of their workflow.
Research
Writers can collect relevant source material before beginning an article.
Content Briefs
Editors can use extracted information to identify important subtopics and questions.
Competitive Analysis
Marketing teams can compare how different websites approach similar subjects.
Knowledge Organization
Businesses can organize publicly available information into research documents or internal references where appropriate.
Content Updating
When updating an existing article, researchers can review current information from relevant sources and identify areas that may require additional research.
The tool itself does not replace editorial judgment. It simply makes the collection stage more efficient.
What Should You Avoid When Extracting Web Content?
Using a content extraction tool responsibly is important.
Avoid Copying Content Without Permission
Extracting publicly accessible information does not automatically give someone the right to republish it.
If you use information from another website, respect copyright, licensing, attribution requirements, and applicable laws.
Don't Create Duplicate Articles
Extracted material should be used for research and analysis rather than creating duplicate versions of existing pages.
For SEO, publishing copied content provides little value and can create quality issues.
Don't Assume Extracted Information Is Automatically Accurate
Extraction tools process webpage structures, but they cannot guarantee that every piece of information is correct or current.
Review important claims against the original source.
Respect Website Restrictions
Always use extraction tools responsibly and respect applicable website terms, access restrictions, robots directives, and rate limits.
Improving Your Research Workflow
A simple workflow can make webpage extraction more useful.
Start by defining the research question. Knowing what you are looking for prevents you from collecting unnecessary information.
Next, identify reliable sources. A smaller number of authoritative sources is often more useful than collecting dozens of irrelevant pages.
After extraction, organize the information by topic rather than simply storing large blocks of text.
Then compare the sources and identify common themes, differences, unanswered questions, and opportunities for additional research.
Finally, create something original from the research. This might be an analysis, guide, comparison, report, or new resource.
Webpage Content Extraction for Modern Digital Workflows
As businesses use more digital tools, the ability to move information efficiently between research and analysis workflows becomes increasingly useful.
A webpage content extractor can serve as a practical bridge between online research and downstream activities such as content planning, competitive research, documentation, and AI-assisted analysis.
The important consideration is how the extracted information is used.
Simply collecting information creates limited value. Organizing, evaluating, and transforming that information into useful original work is where the real benefit comes from.
Final Thoughts
Webpage content extraction can simplify an otherwise repetitive part of online research. Instead of manually copying information from complex webpages, users can use extraction tools to collect relevant content and prepare it for review.
The WhisperChat Webpage Content Extractor can be considered as one option for workflows involving research, content analysis, and information organization. Users can provide a webpage and configure the information they want to work with.
The best results come when extraction is combined with careful source evaluation, human review, original analysis, and responsible content practices.
For SEO professionals and content writers in particular, the goal should not be to reproduce what already exists online. The stronger approach is to use extracted information as research material, identify what is missing or unclear, and then create something more useful for the reader.
That approach turns webpage extraction from a simple copy-and-paste shortcut into a practical part of a broader research and content-development workflow.
SEO and content writer interested in AI, SaaS, digital marketing, and content strategy. I create original, useful content focused on practical technology, SEO, and business solutions while following natural, reader-first content practices. Website: https://www.whisperchat.ai/demo
Comments (0)